
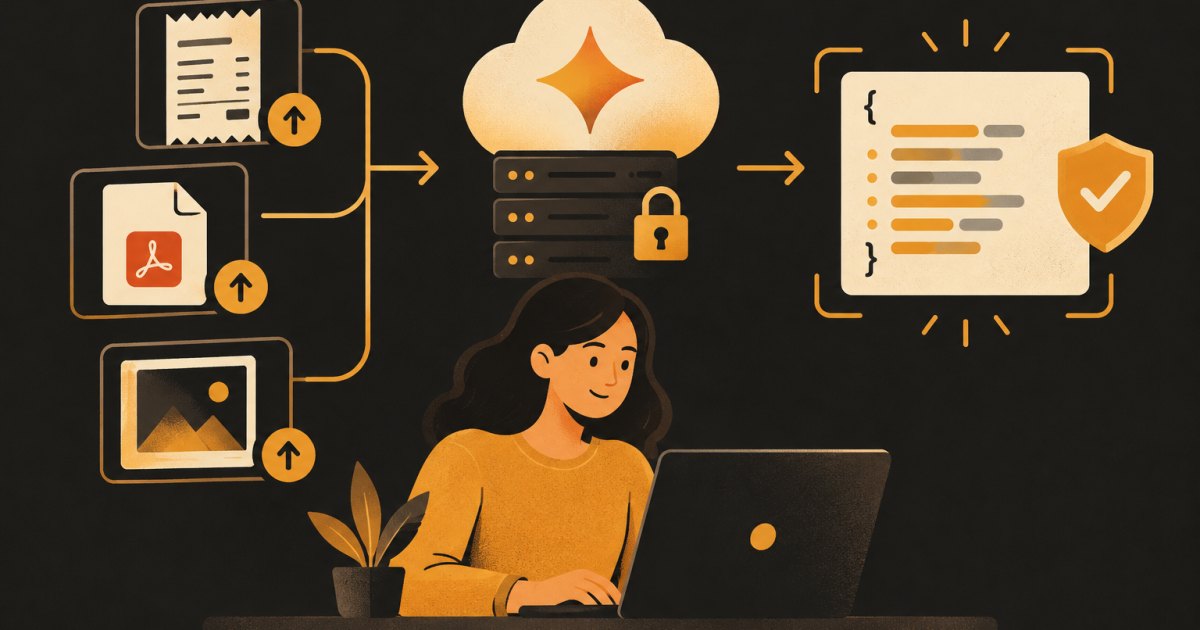
This post is for people already shipping apps. You have users, a backend you control (a Node server, a serverless function or a Supabase Edge Function) and you want to add a feature like "upload a receipt and we fill in the expense" or "drop in a PDF invoice and we extract the line items."
Gemini models take images and PDFs as input, and the API can return JSON that matches a schema you define. Together, that covers most document-reading features a small SaaS needs.
The architecture
Keep it boring:
- The user uploads a file in your app.
- Your server receives it, checks type and size, and sends it to Gemini with a prompt and a schema.
- Gemini returns JSON.
- Your server validates the JSON, then saves it as a draft the user confirms.
The Gemini API key lives only on the server, in an environment variable named GEMINI_API_KEY. The browser never sees it. If you need to call Gemini straight from a mobile or web client, Google's supported route is Firebase AI Logic with App Check, not a raw key in the app.
A note on the API shape
Google now recommends the Interactions API (client.interactions.create) for new work. The older generateContent method is still supported, so existing code does not need to change today. The examples below use Interactions with the official @google/genai package. The SDK has changed shape this year, so compare against the current docs before you copy anything into production.
Step 1: Define the schema
Decide exactly what you want back. For a receipt:
const receiptSchema = {
  type: "object",
  properties: {
    merchant: { type: "string" },
    date: { type: "string", description: "YYYY-MM-DD" },
    currency: { type: "string", description: "ISO code like USD" },
    total: { type: "number" },
    tax: { type: "number" },
    line_items: {
      type: "array",
      items: {
        type: "object",
        properties: {
          description: { type: "string" },
          amount: { type: "number" }
        },
        required: ["description", "amount"]
      }
    },
    confidence: { type: "string", enum: ["high", "medium", "low"] }
  },
  required: ["merchant", "date", "total", "confidence"]
};
Two design choices worth copying. The confidence field gives the model a way to say "this photo was hard to read," which you can use in the UI. And only the fields you truly need are required. Forcing a tax value on a receipt with no tax line invites the model to make one up.
Step 2: Send an image with the schema
Images under the inline limit (Google's docs put the total request at 20MB) can be sent as base64. Supported image types include PNG, JPEG, WEBP, HEIC and HEIF.
import { GoogleGenAI } from "@google/genai";

const client = new GoogleGenAI({}); // reads GEMINI_API_KEY

export async function readReceipt(base64Image, mimeType) {
  const interaction = await client.interactions.create({
    model: "gemini-3.8-flash",
    input: [
      {
        type: "text",
        text:
          "Extract the receipt details. Use only what is printed " +
          "on the receipt. If a field is unreadable, leave it out " +
          "and set confidence to low. Do not guess totals."
      },
      { type: "image", data: base64Image, mime_type: mimeType }
    ],
    response_format: {
      type: "text",
      mime_type: "application/json",
      schema: receiptSchema
    }
  });

  return JSON.parse(interaction.output_text);
}
For most extraction jobs, a Flash model is the right default: fast and cheaper than the flagship. Move up only if your accuracy tests say you need to. Check the models page for current names before you deploy, since they change often.
Step 3: Handle PDFs and screenshots
PDFs work almost the same way. Change the part type to document:
{ type: "document", data: base64Pdf, mime_type: "application/pdf" }According to Google's document processing docs, PDFs can be up to 50MB or 1,000 pages. For large files, or a file you will query more than once, upload it with the Files API first (client.files.upload) and pass its uri instead of the data. Uploaded files are kept for 48 hours, so do not treat the Files API as storage. Keep the original in your own storage bucket.
Screenshots are just images. They are useful for features like "upload a screenshot of your bank's transaction page" or "send us a screenshot of the error." The same schema approach works: define the fields, send the image, validate the result.
Step 4: Validate before you save
Structured output guarantees valid JSON in the shape you asked for. It does not guarantee the values are right. Google's own structured output docs say to validate in your application, and they note that some schema rules (like minLength and maxLength) are ignored by the API rather than enforced.
The docs show Zod for this in JavaScript. At minimum, check:
- Math. Do the line items roughly add up to the total? If not, flag it.
- Dates. Is the date a real date, and not in the future?
- Ranges. A coffee receipt for 4,800 dollars is probably a misread decimal.
- Confidence. If it is low, show the fields as empty and ask the user to fill them in.
Step 5: Make the user confirm
Never write extracted data straight into records that matter (expenses, invoices, anything financial). Save it as a draft and show a review screen with the original image next to the extracted fields. One click to confirm, easy edits for mistakes.
This also gives you free quality data. Every time a user corrects a field, log what the model said and what the user changed it to. After a few hundred corrections you will know exactly which receipts and fields cause trouble, and whether a prompt change or a different model would help.
Production checklist
- Check file type and size on the server, not just in the browser.
- Rate limit per user. Image and PDF requests use more tokens than text.
- Log token usage per request so you can price the feature. Each PDF page counts as a fixed number of tokens, so long documents add up.
- Tell users what happens to their files. Receipts and invoices can contain personal data. Review Google's terms for the API tier you use and update your privacy policy.
- Build a small test set. Twenty real receipts with the correct answers written down. Run them after every prompt or model change.
Where to go next
The recipes include build specs that follow this upload, extract, review pattern on a Supabase backend. If you want a second set of eyes on your schema or validation before launch, bring it to a cohort.
What would have made it better?